Cognee Alternatives: What You Are Actually Replacing
On this page, 10 sections
Step two of the Cognee quickstart, copied from its README on 2 September 2026:
import os
os.environ["LLM_API_KEY"] = "YOUR OPENAI_API_KEY"
That line is why most people end up searching for a Cognee alternative. It is not a bug and Cognee is not hiding it.
It is a design commitment: the pipeline builds a knowledge graph by having a model read your data, so a model has to read your data.
Everything that follows, the per-item cost, the vendor dependency, the fact that ingestion speed is governed by somebody else’s rate limits, comes out of that one line.
There are three separate reasons to leave, and they point at three different replacements. Picking the wrong one gets you a project with the same constraint under a different name.
Graphiti, the most commonly recommended swap, also defaults to OpenAI for both inference and embeddings. If you left Cognee over LLM cost, you have moved sideways.
What you are actually replacing
Cognee is a pipeline that turns documents into a graph plus a vector index, exposed through four operations its README names as remember, recall, forget and improve.
Local development runs fully embedded on SQLite, LanceDB and Kuzu, with no external services to stand up. Licence is Apache 2.0. As of 2 September 2026 the repository shows 30.4k stars.
Three things about it drive people to the search box.
1. The model is in the read path too, not only the write path
From the performance tuning section of the README: AUTO_FEEDBACK=false “removes the one LLM call cognee makes after each answered query to self-tune its memory”.
That is a per-query charge on top of the per-document ingestion charge, and it is on by default. If you budgeted for ingestion only, your bill will not match your model.
The same section contains a warning worth repeating, because it invalidates a lot of comparison blog posts: CACHING=false disables session memory entirely, and the README says “If you’re benchmarking cognee, leave it on – turning it off benchmarks cognee with its memory layer removed.” Anyone who published a head-to-head with caching disabled measured something else.
2. Parts of what looks open are on the other side of a commercial line
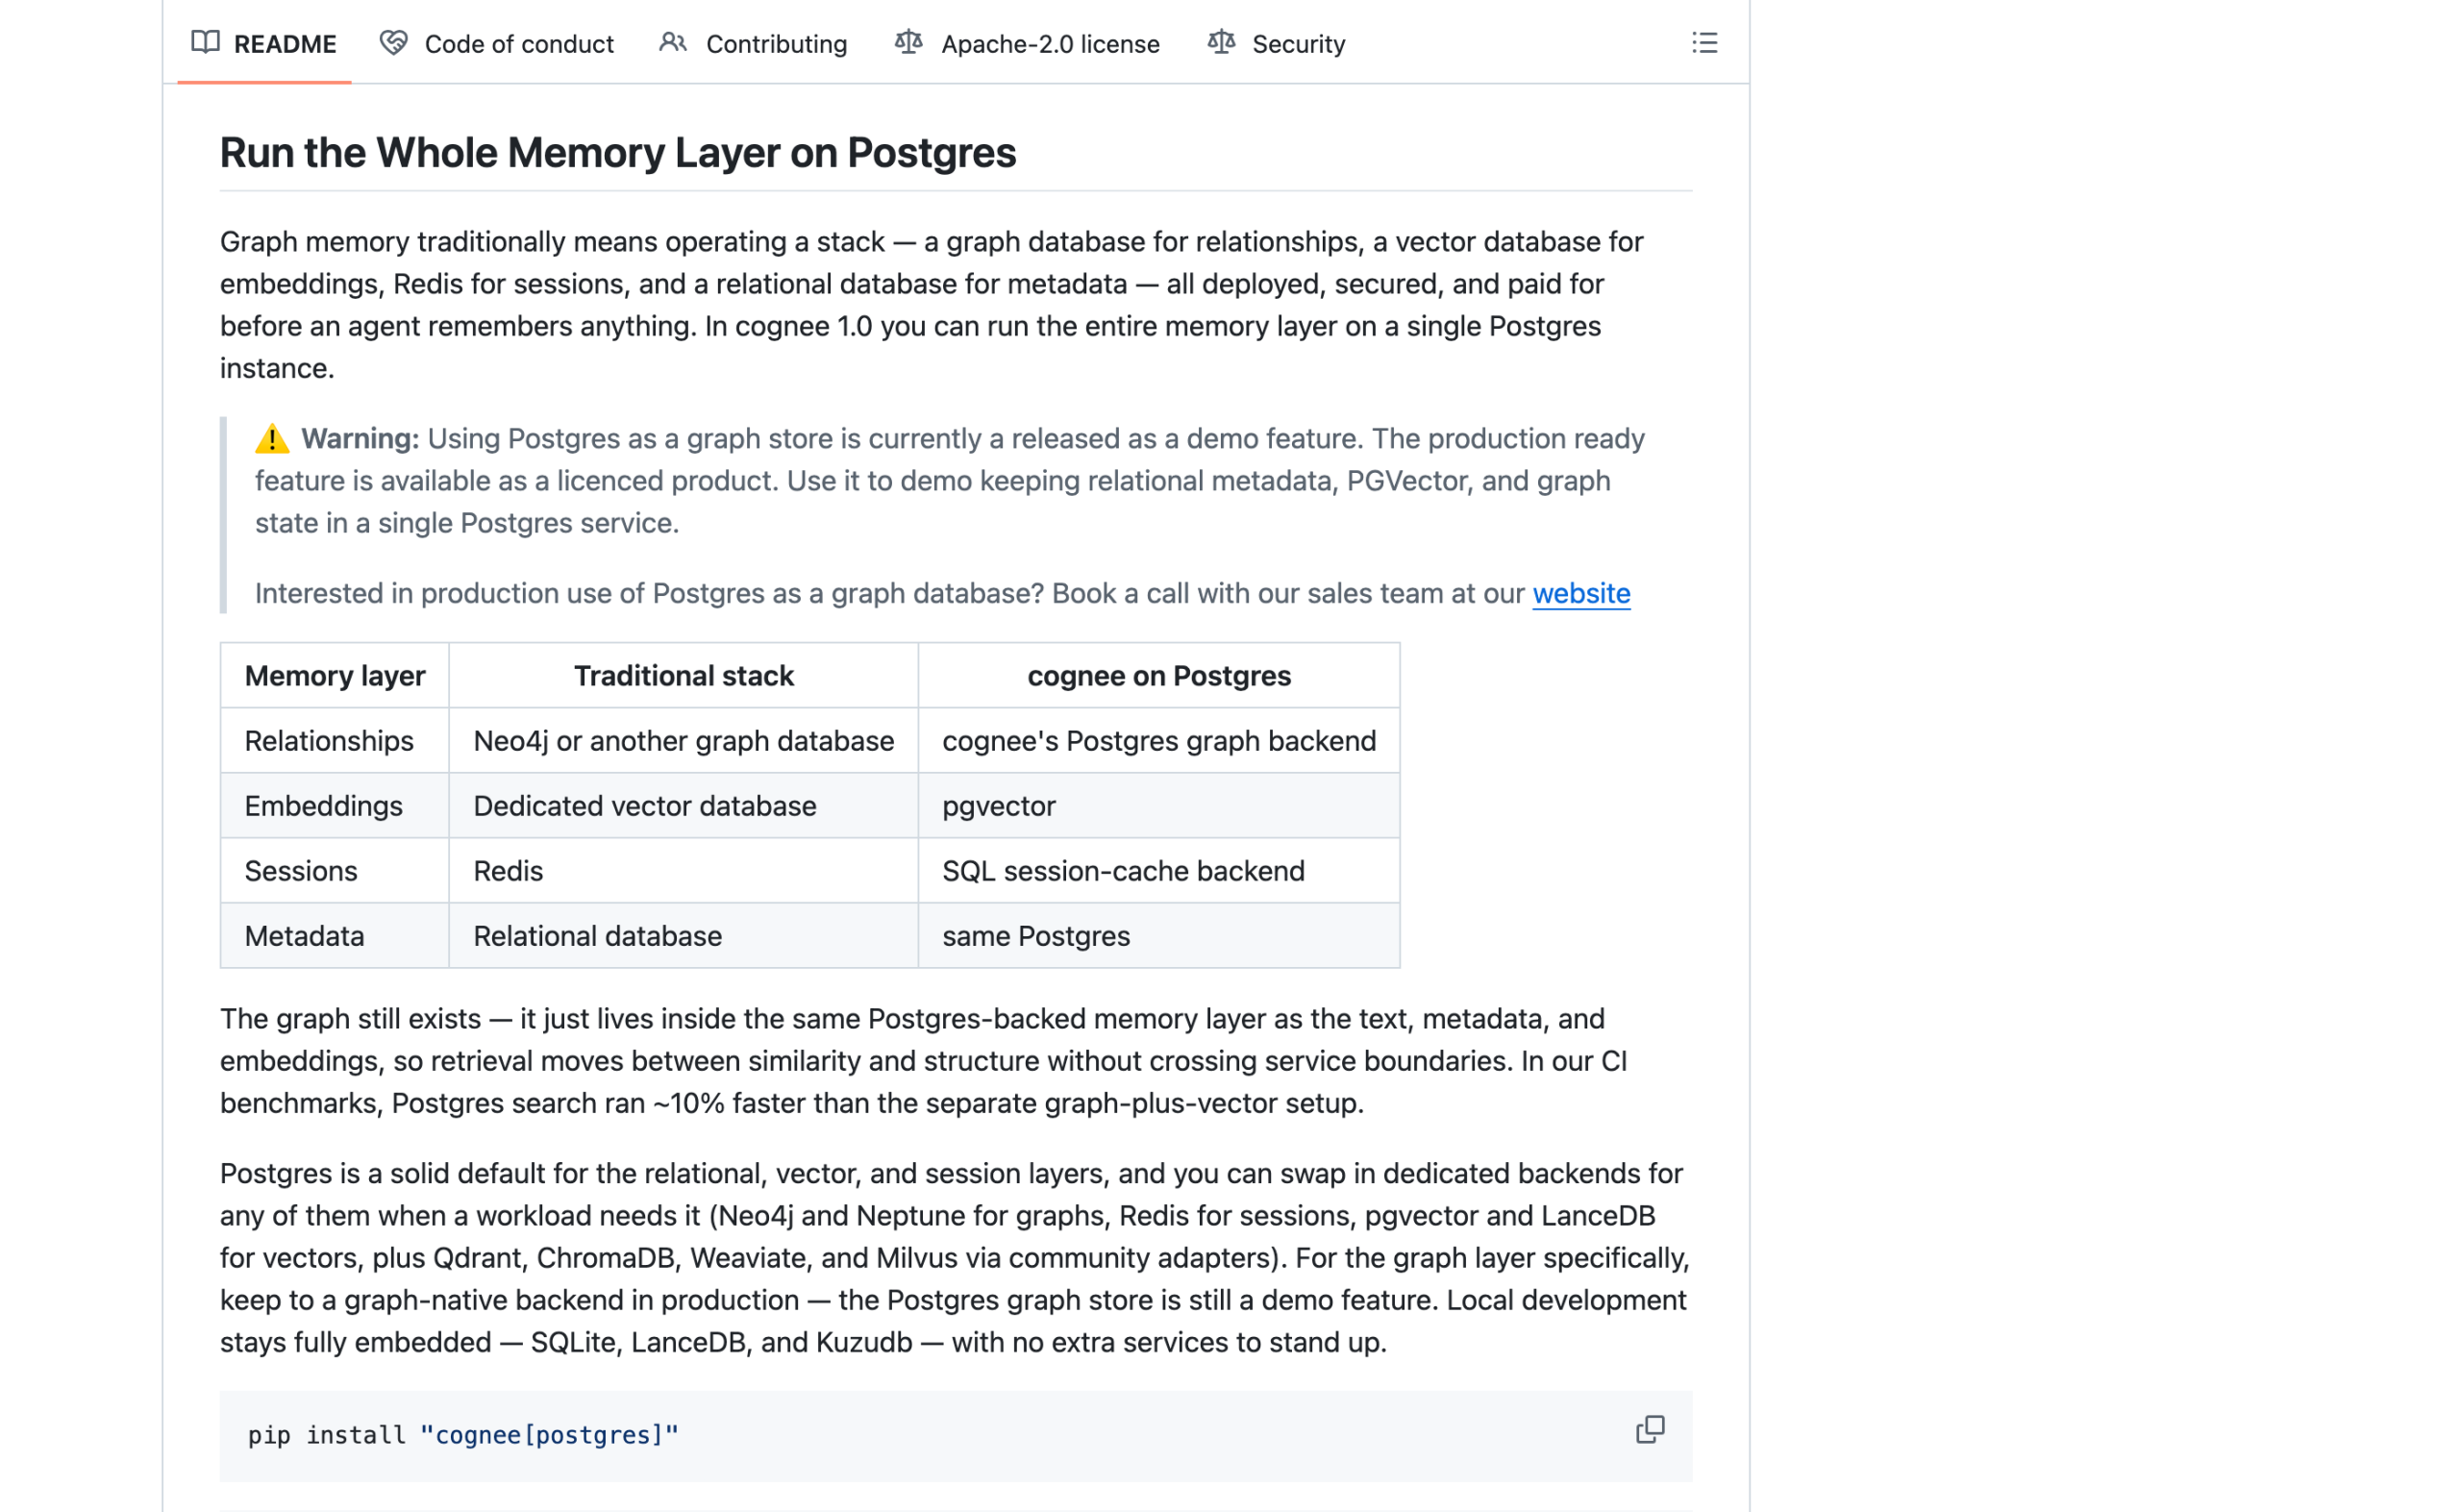
The README’s headline feature for version 1.0 is running the whole memory layer on a single Postgres instance instead of a graph database plus a vector database plus Redis plus a relational store. Directly under it:
Using Postgres as a graph store is currently a released as a demo feature. The production ready feature is available as a licenced product.
Cognee README, read 2 September 2026
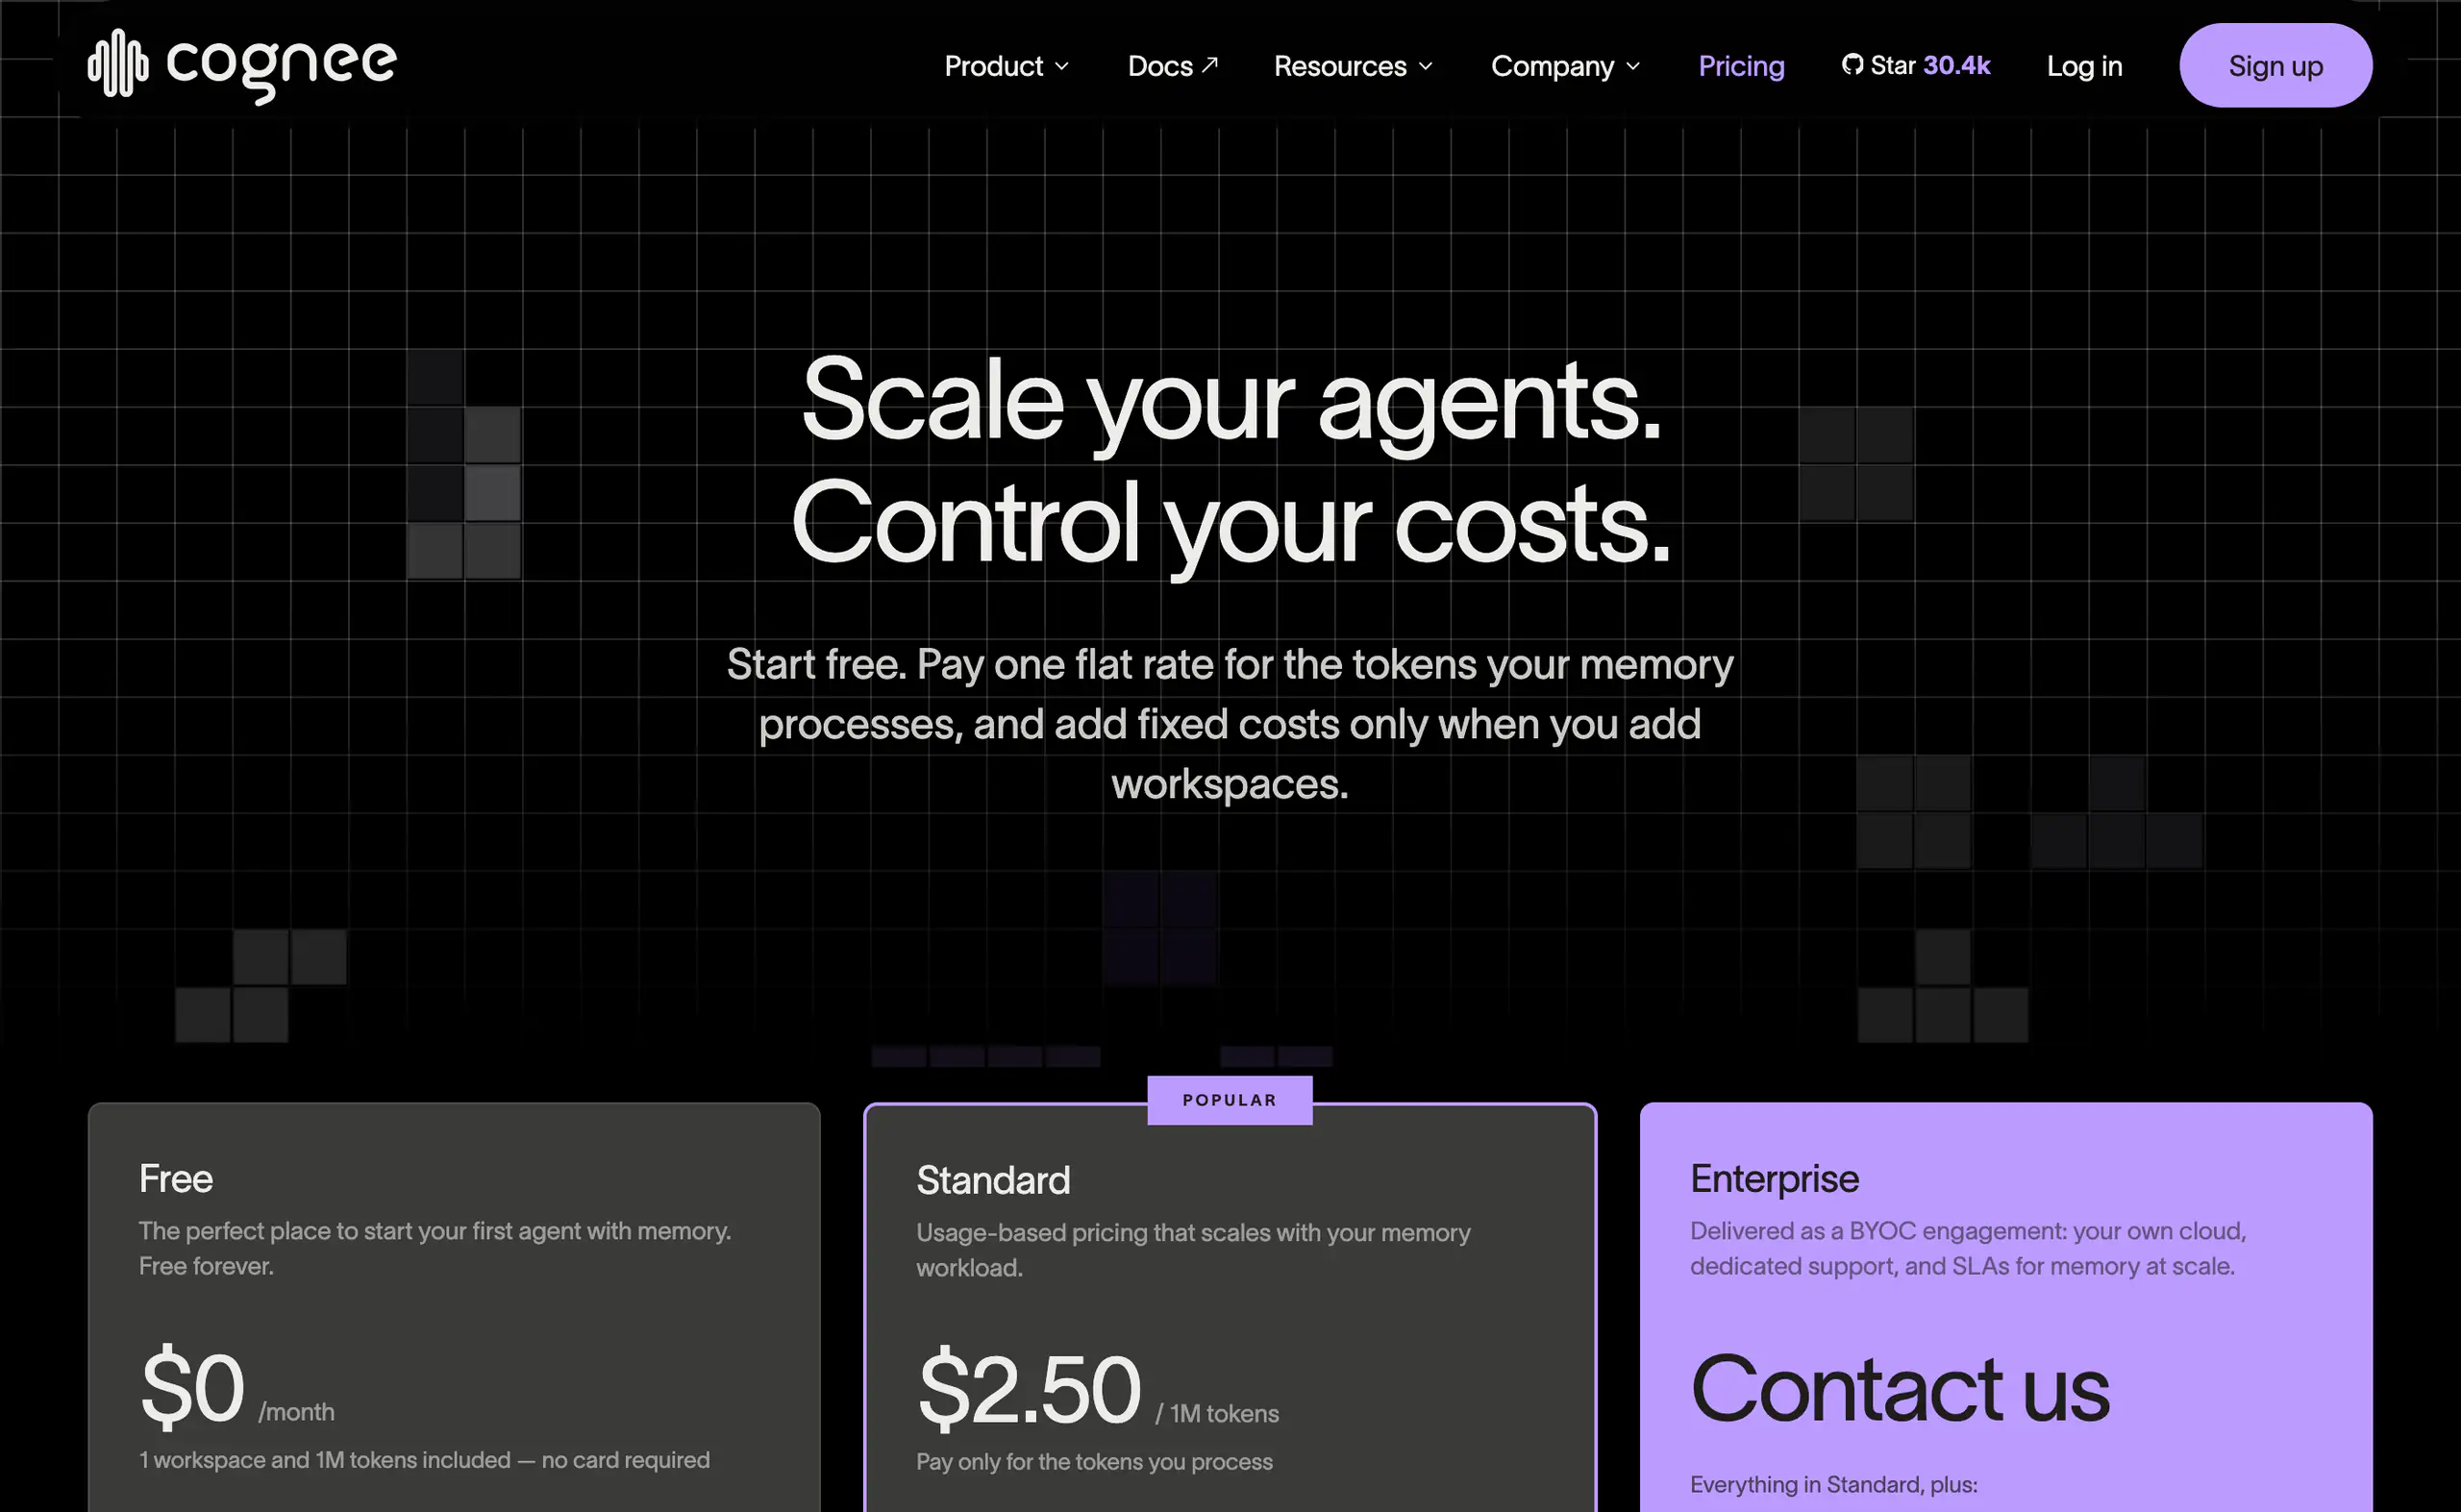
The pricing page draws the same line elsewhere. On cognee.ai/pricing, read 2 September 2026, bi-temporal memory with conflict resolution, provenance on every answer, and per-user personalisation are listed under Enterprise, delivered as a bring-your-own-cloud engagement.
The Standard tier is $2.50 per 1M tokens processed plus $5 per additional workspace, and the free tier is 1M tokens with one workspace.
This is a legitimate open-core business and I have no complaint about it. It matters only because bi-temporal memory is the exact capability Graphiti ships in its Apache 2.0 core.
If that is what you came for, the alternative is not a downgrade.
3. Backend choice is a hard constraint, not a preference
With ENABLE_BACKEND_ACCESS_CONTROL=true, the default, each user and dataset combination gets isolated graph and vector databases. Both layers have to support isolation. Neptune, remote Ladybug and the community vector adapters do not.
Cognee raises an error naming the unsupported backend rather than silently falling back to shared databases, which is the right behaviour and also means you cannot discover this problem gradually. You discover it when you switch.
The alternatives, on checkable properties
| Project | Licence | Stars, 2 Sep 2026 | LLM needed to index? | Storage shape |
|---|---|---|---|---|
| Cognee | Apache 2.0 | 30.4k | Yes, plus one call per answered query by default | Graph plus vector, embedded locally or Postgres |
| Graphiti | Apache 2.0 | 30.5k | Yes, defaults to OpenAI for both LLM and embeddings | Bi-temporal graph, bring your own graph DB |
| mem0 | Apache 2.0 | 64.6k | Yes, one call per add | Vector store plus extracted facts |
| LightRAG | MIT | 39.3k | Yes, an EXTRACT role model | Graph plus vector, many backends |
| MemPalace | MIT | 58.8k | No, local embeddings on the default path | Verbatim drawers plus SQLite temporal graph |
Of those five, exactly one will index your data without an API key. That is the single most useful sorting fact in this category, and it is checkable in five minutes from the READMEs.
Graphiti, if you left for the temporal graph
Graphiti is the open-source temporal graph engine underneath Zep. Facts are triples with validity windows, so nothing is deleted when it changes, it is invalidated and the history stays queryable.
Entities and relationships trace back to episodes, the raw ingested data, which gives you provenance in the core rather than on an enterprise plan.
Entity and edge types are defined with Pydantic models, or left to emerge from the data.
What it costs to run
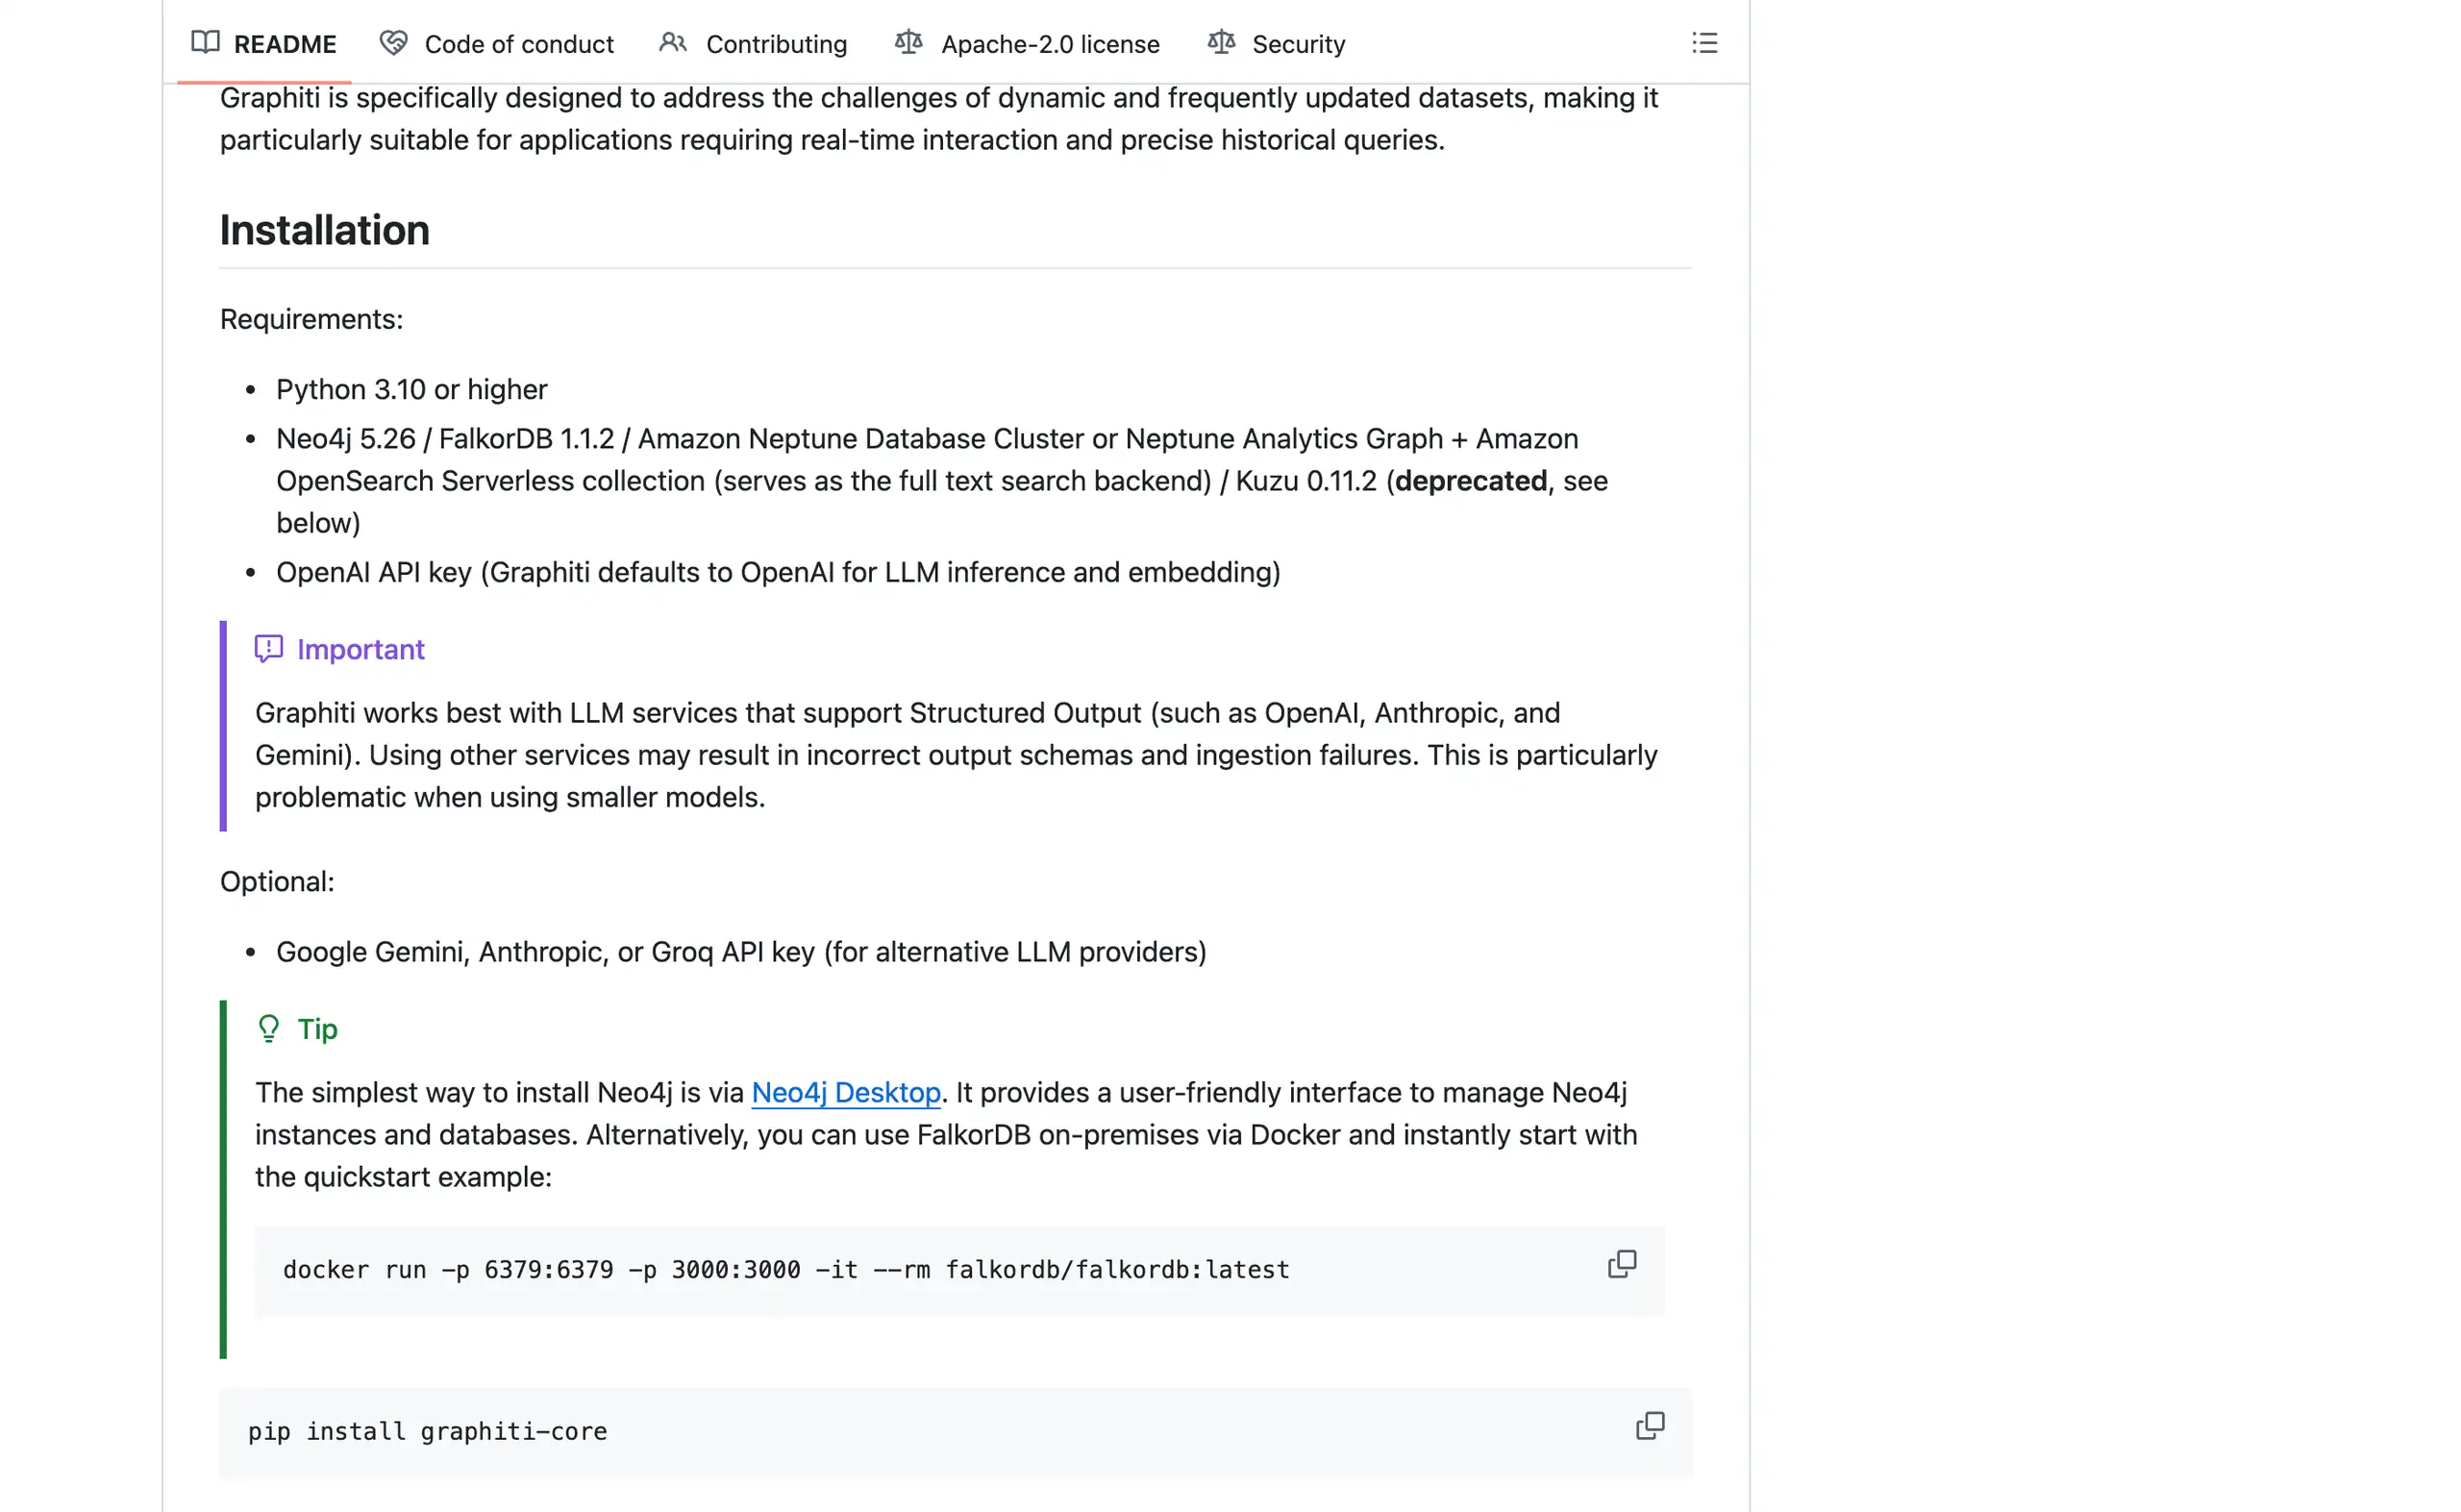
The operational cost of that is stated plainly in the installation requirements: Python 3.10 or higher, plus Neo4j 5.26, or FalkorDB 1.1.2, or an Amazon Neptune cluster together with an OpenSearch Serverless collection for full-text search.
Kuzu is still listed and is deprecated, because the upstream project is no longer maintained. If you built on the embedded Kuzu path to avoid running a database, that path is closing.
Two details that decide it for you
Two more details from the README that decide whether this works for you. Graphiti “works best with LLM services that support Structured Output”, and using others “may result in incorrect output schemas and ingestion failures”, which the docs note is worse with smaller models.
And SEMAPHORE_LIMIT ships at 10 concurrent operations specifically to avoid 429 rate limit errors from your provider. Ingestion throughput and API spend are the same dial.
pip install graphiti-core
# or with a graph backend that runs in one container
pip install graphiti-core[falkordb]
docker run -p 6379:6379 -p 3000:3000 -it --rm falkordb/falkordb:latestMemPalace, if you left for the LLM bill
This is the only alternative here that removes the constraint rather than relocating it.
Content is stored verbatim, embeddings are computed locally by a model on your disk, roughly 30 MB for MiniLM or 300 MB for embeddinggemma-300m, and the README states that no API key is required for the core path.
Licence is MIT. It ships 45 MCP tools and auto-save hooks for Claude Code, Codex CLI and Cursor.
What you give up with MemPalace
Be clear about what you give up. You get retrieval, a structured index and a temporal knowledge graph. You do not get Cognee’s ontology generation or its per-document-type entity extraction.
If the custom pipeline is your product, this is the wrong swap. If the pipeline was plumbing you tolerated to get search over your own history, it is the right one.
I go through that trade in detail in mem0 vs MemPalace, where the benchmark numbers are not measuring the same thing.
LightRAG, if you wanted the pipeline without the platform
LightRAG from HKUDS is the closest thing to Cognee’s shape that does not present itself as a memory platform.
Its README documents role-specific LLM configuration with four distinct roles, EXTRACT, QUERY, KEYWORDS and VLM, each independently configurable, which is genuinely useful if you want a cheap model doing extraction and a strong one answering.
It offers four chunking strategies, a reranker as the default query mode, document deletion with automatic knowledge graph regeneration, and storage on Postgres, Neo4j, MongoDB or OpenSearch.
RAG-Anything was merged into it in May 2026 for multimodal parsing through MinerU or Docling.
Licence is MIT, 39.3k stars, and the latest release tagged on 2 September 2026 is v1.5.7, which tells you the project is being worked on today rather than last spring.
It still needs a model for extraction. What it gives you is control over which model, per role.
Letta: read the repository before you shortlist it
Letta appears on most 2026 alternatives lists, including my own comparison of AI memory tools for a second brain. Check the repository yourself before you act on any of them.
As of 2 September 2026, letta-ai/letta states that it “now serves as a landing page for the Letta project”.
The V1 server source lives on an archive branch and the README says it “is unsupported, receives no fixes or security updates, and should not be used in production”.
Active development moved to letta-ai/letta-code. The last release tagged on the old repository is v0.16.8, 14 May 2026.
Why alternatives lists go stale
This is the general failure mode of alternatives lists, mine included. They are snapshots. In the four and a half months since I published that comparison, mem0 went from 53k stars to 64.6k, MemPalace from 46.7k to 58.8k, and Cognee from 15.5k to 30.4k.
Anything you read about this category that has not been rechecked this month is describing a different field.
The comparison nobody has published
There is no run of these five systems on one dataset, with one metric, one reader model and one hardware configuration, by anyone without a stake in the outcome.
I have not done it either, and I am not going to imply otherwise with a table of numbers scraped from five different experiments.
Every project says its own number is not comparable
Each project is honest about this in its own documentation, which is worth noticing. Cognee’s BEAM results come with the caveat that they are “a directional signal rather than a definitive measure”.
MemPalace refuses to publish a side-by-side against its competitors because retrieval recall and end-to-end QA accuracy are different quantities. mem0 marks its headline scores as platform numbers with proprietary optimisations not present in the open-source SDK.
Three projects saying “our number is not comparable to theirs” is a stronger signal than any of the numbers.
How to read a benchmark claim
Do the same thing you would do with any vendor claim: separate the headline from the mechanism, and verify only the mechanism, because that is the half you can check from outside.
It is the method that caught a real problem when the commercial malware scanners reported a site clean while it was serving spam to Googlebot.
The scores were confident. The mechanism could not have detected the thing that was happening.
How to choose in ten minutes
Answer one question and the shortlist collapses.
- Leaving over cost or over sending data to a provider? MemPalace. It is the only one of the five that indexes without a model.
- Leaving because bi-temporal reasoning is on the Enterprise plan? Graphiti. Same capability, Apache 2.0, at the price of running Neo4j or FalkorDB.
- Leaving because you want a pipeline you control per stage? LightRAG. Role-specific models are the feature that matters.
- Leaving because you want the largest ecosystem and drop-in integrations? mem0.
- Leaving because the ops surface is too big? Postgres with pgvector and your own hundred lines. Cognee’s own 1.0 release note argues that collapsing four services into one Postgres is viable, and if it is viable for them it is viable for you.
Cost the new stack before you move
Before you migrate anything, work out what the new stack costs at your real volume.
The arithmetic is in what self-hosted AI memory actually costs to run, and for most solo builders the answer is small enough that licence and data ownership should decide instead.
And if you are wiring any of these into a coding agent, the practical limits I hit doing that against production systems are in running Claude Code against WordPress.
More on ai memory and mcp
- mem0 vs MemPalace: The Benchmark Numbers Are Not Measuring the Same Thing
- What Self-Hosted AI Memory Actually Costs to Run
- MCP Server vs RAG: Which One You Actually Need
Resources
- Cognee repository: github.com/topoteretes/cognee
- Cognee documentation: docs.cognee.ai
- Cognee pricing: cognee.ai/pricing
- Cognee paper, Markovic et al. 2025: arXiv 2505.24478
- Graphiti repository: github.com/getzep/graphiti
- Zep temporal knowledge graph paper: arXiv 2501.13956
- MemPalace repository: github.com/MemPalace/mempalace
- LightRAG repository: github.com/HKUDS/LightRAG
- Letta, current source: github.com/letta-ai/letta-code